Table of Contents
Retrieval-Augmented Generation can only retrieve what the query allows it to discover. That sounds obvious, but it points to one of the most overlooked weaknesses in many RAG systems.
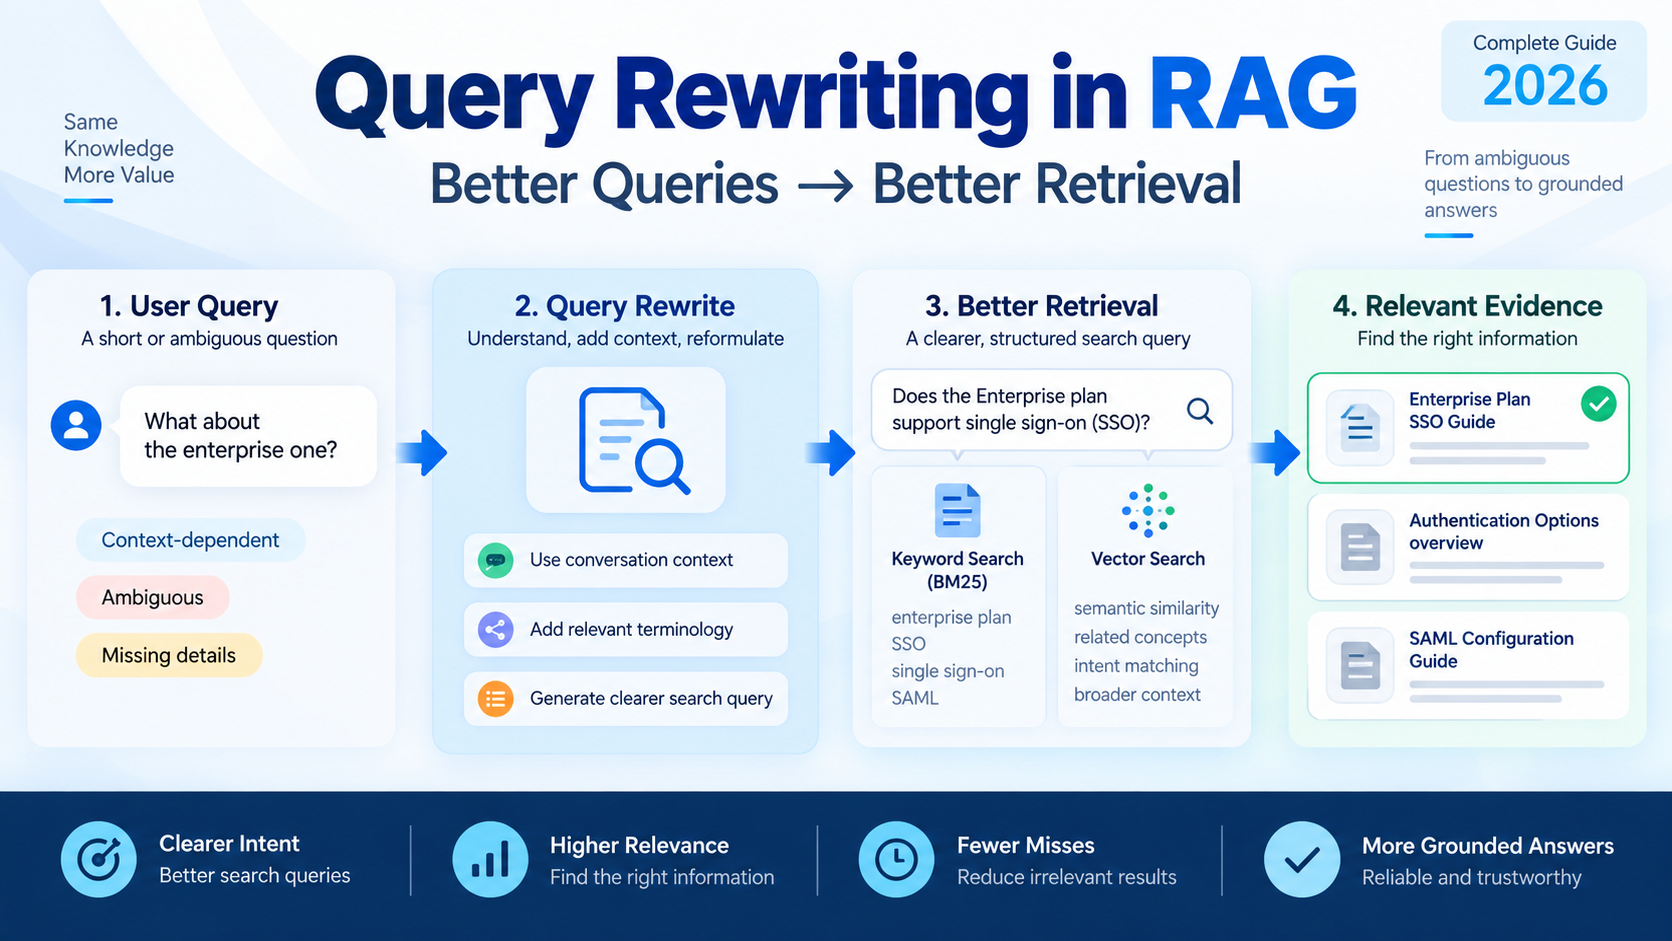
A user might ask, “What about the enterprise plan?”
A human reading the conversation knows exactly what that means. A retrieval system that receives that sentence in isolation may not understand which enterprise plan it refers to or what the pricing is.
This scenario is where query rewriting in RAG becomes valuable. Instead of sending every user question directly to the retriever, the system first transforms it into a clearer, more searchable query.
The rewritten query can resolve missing context, add useful terminology, break a complicated question into smaller searches, or generate alternative ways of expressing the same information need. In practical RAG systems, better retrieval is therefore not only about better embeddings, better chunking or a better vector database.
Occasionally the biggest improvement starts before retrieval even begins. This guide explains how query rewriting works, the main query transformation strategies, where it fits alongside hybrid search and reranking, and when adding another LLM call actually makes sense.
What Is Query Rewriting in RAG?
In RAG, query rewriting refers to the process of transforming the user’s initial question into a query that is better suited to retrieve relevant information from the knowledge base.
The core workflow is as follows:
User Query → Query Rewriter → Enhanced Search Query → Retriever → Relevant Documents → LLM → Answer
Consider a support conversation:
User: Does the Pro plan support SSO?
Later on:
What about the enterprise one?
If you’re searching for “What about the enterprise one?”, you’re unlikely to find a good result, as the query has lost the subject of the conversation.
A query rewriter might rewrite it to:
“Does the Enterprise plan support single sign-on (SSO)?”
The underlying knowledge base was not changed. No change to the vector database. The embedding model was the same.
What changed was how the user’s information need was represented. That difference can significantly affect what the retriever returns.
If you are new to the overall architecture, you should start with my Retrieval-Augmented Generation (RAG) Complete Guide 2026, which explains how retrieval and generation work together before these more advanced optimisation layers come in.
Why RAG Systems Struggle With Real User Queries
Many RAG examples begin with beautifully written questions:
“What is the company’s refund policy on annual subscriptions?”
Real users are seldom so cooperative. They ask questions like:
- “Can I have my money back?”
- “What if I paid yearly?”
- “Business accounts too?”
- “Is it the same outside of India?”
Each of these questions may be inadequate. Their meaning depends on preceding turns.
There are several common problems.
Conversational ambiguity
Pronouns and phrases such as ‘it’, ‘that plan‘, ‘the previous one‘, ‘what about this’, or ‘does it still apply’ depend on conversation history.
A retriever cannot safely assume that the surrounding context will automatically be represented in the query embedding.
Vocabulary mismatch
Users and documents may describe the same concept differently.
A user searches for:
“employee login through company account”
while the documentation uses:
“enterprise SAML single sign-on.”
Semantic retrieval helps with this problem, but terminology differences can still reduce retrieval quality.
Overly broad questions
Think about:
“Tell me about your security.”
A knowledge base may have hundreds of chunks about authentication, encryption, access control, audit logs, data residency and compliance.
Precision of retrieval is not possible until the query is more precise.
Multi-part questions
A user may also ask:
Compare enterprise and pro plans for SSO, audit logs and data retention.
That is not necessarily a simple retrieval problem.
It might actually be several:
- Enterprise SSO
- For SSO
- Enterprise audit logging
- Audit logging pro-
- Enterprise retention policies
- Support retention policy
A single broad vector search may miss some of those pieces. Query transformation allows the RAG system to identify the structure before it searches.
Query Rewriting vs Query Expansion vs Query Decomposition
These terms are related, but they should not be treated as identical.
| Technique | What it does | Example |
|---|---|---|
| Query rewriting | Restates the query more clearly | “What about Enterprise?” → “Does the Enterprise plan support SSO?” |
| Query expansion | Adds related terms or alternate expressions | “SSO” → “SSO, single sign-on, SAML authentication” |
| Multi-query generation | Produces several alternative searches | Generate 3–5 formulations of the same information need. |
| Query decomposition | Splits a complex question into smaller questions | Break a comparison into separate feature searches. |
| Hypothetical document retrieval | Generates a likely answer/document representation for retrieval | Create a hypothetical relevant passage, then search using its embedding |
All of them belong to a broader family that we can call query transformation.
The right technique depends on why retrieval is failing.
How Query Rewriting Works in a RAG Pipeline
A basic RAG pipeline might look like this:
Question → Embedding → Vector Search → Retrieved Chunks → LLM
An advanced retrieval pipeline can look more like:
Question
↓
Query Analysis / Rewriting
↓
Sparse + Dense Retrieval
↓
Fusion
↓
Reranking
↓
Evidence Selection
↓
LLM
This distinction matters.
- Query rewriting improves what you search for.
- Hybrid search improves how you search.
- Reranking improves which retrieved candidates deserve priority.
These components solve different problems and can work together.
My Hybrid Search Complete Guide 2026 explains why combining lexical and semantic retrieval often gives RAG systems a broader candidate set, while the Reranking in RAG Complete Guide 2026 explains how stronger relevance models can reorder those candidates before they reach the LLM.
Query rewriting sits naturally before both.
Strategy 1: Rewrite Conversational Questions Into Standalone Queries
This method is one of the most practical applications of query rewriting.
Imagine this conversation:
User: What is the refund period for annual subscriptions?
Assistant: Annual subscriptions can be refunded within the conditions described in the refund policy.
User: Does that apply to enterprise customers too?
The second query contains context, but it is not fully independent.
A rewriter can produce:
“Does the annual subscription refund policy apply to Enterprise customers?”
Now the retriever has a much cleaner representation of the question.
This becomes particularly useful for:
- customer-support assistants
- enterprise knowledge assistants
- documentation chatbots
- multi-turn research tools
- internal company copilots
Recent SemEval-2026 work on multi-turn RAG specifically focuses on this problem: context-dependent follow-up questions need to be transformed into useful standalone retrieval queries.
Strategy 2: Query Expansion
Sometimes the original query is clear but too narrow.
Suppose the user asks:
“How do I configure SSO?”
Possible expansion:
“Configure SSO, single sign-on, SAML authentication, identity provider integration.”
The additional terms create more opportunities to match relevant documents.
This is especially helpful for lexical retrieval because keyword-based search depends heavily on term overlap.
But expansion can also become dangerous. Adding too many loosely related terms can change the intent and introduce irrelevant documents.
The objective is not “to make the query longer”.
It is “to make the information needed easier to retrieve.”
Strategy 3: Multi-Query Retrieval
Instead of trying to create one perfect query, a system can generate several.
Original question:
“How does RAG reduce hallucinations?”
Possible generated queries:
- How does retrieved context improve LLM factual accuracy?
- How does Retrieval-Augmented Generation ground LLM responses?
- Why can external knowledge reduce hallucination in language models?
Each query can retrieve a slightly different candidate set. The results are then merged, deduplicated and potentially reranked.
This approach can improve recall when relevant documents use different terminology. However, more queries also mean:
- more retrieval operations
- more candidates
- more latency
- greater reranking workload
- potentially more noise
More queries are not automatically better than other queries. That distinction becomes important in production systems.
Strategy 4: Query Decomposition for Complex Questions
Some questions contain multiple information needs that should not be forced into one search.
Consider:
“Which plan is better for a 500-person company if we need SSO, audit logs and 12-month data retention?”
A query decomposition stage might create:
Query 1: Enterprise plan SSO support
Query 2: Enterprise plan audit logs
Query 3: Enterprise data retention period
Query 4: Pro plan SSO support
Query 5: Pro plan audit logs
Query 6: Pro plan data retention period
The system retrieves evidence for each sub-question and then combines it before generation.
This is particularly useful for:
- comparison questions
- multi-hop reasoning
- research assistants
- financial analysis
- policy analysis
- technical troubleshooting
It also foreshadows Agentic RAG, where the system can decide that additional searches are required instead of relying on one predetermined retrieval operation.
Strategy 5: Hypothetical Document Embeddings (HyDE)
HyDE takes a different approach. Instead of searching directly with the user’s short question, an LLM generates a hypothetical document or passage that might answer it.
Suppose the query is:
“Why does hybrid search improve RAG?”
The model could generate a short hypothetical explanation containing concepts such as:
- lexical retrieval
- semantic similarity
- BM25
- dense vectors
- retrieval recall
The system embeds the generated passage and searches for real documents that have similar representations.
The hypothetical answer does not need to be factually perfect. Its purpose is to create a richer semantic search representation. This can be useful when the original query contains too little information for effective dense retrieval.
But because an LLM is generating additional content before retrieval, HyDE should be evaluated carefully for domain-specific workloads rather than enabled by default.
Query Rewriting + Hybrid Search + Reranking
This scenario is where modern RAG architecture becomes particularly interesting.
A strong retrieval pipeline can use all three:
User Query
↓
Query Rewriting
↓
Rewritten / Expanded Queries
↓
Keyword Search + Vector Search
↓
Candidate Fusion
↓
Cross-Encoder Reranking
↓
Top Evidence
↓
LLM
Each stage has a distinct job.
- Query rewriting: Improves the search request.
- Hybrid retrieval: Improves candidate discovery.
- Reranking: Improves candidate ordering.
- Evidence selection: Controls what actually enters the context window.
This layered architecture is not merely theoretical. Several systems submitted to SemEval-2026’s multi-turn RAG evaluation used variations of this pattern.
One system that combined controlled query rewriting, dense and sparse retrieval, and cross-encoder reranking achieved an nDCG@5 of 0.5453, ranking 3rd among 38 teams in its retrieval task.
Another system combining LLM-based query rewriting with sparse-dense retrieval reported that query rewriting was its most impactful retrieval component.
Those results do not mean every application should copy the same architecture. They do show why query quality deserves to be treated as a first-class retrieval problem.
Where Embeddings Fit Into Query Rewriting
Query rewriting does not replace embeddings. It changes the text that gets embedded.
Suppose:
Original query:
“Does it work with Azure?”
After conversation-aware rewriting:
Rewritten query:
“Does the Enterprise SSO feature integrate with Microsoft Azure Active Directory?”
The embedding model can now represent a much richer information need.
The same vector database may therefore return substantially better candidates simply because its input became more informative.
If the relationship between text, vectors and semantic similarity is unfamiliar, my AI Embeddings Complete Guide 2026 explains that layer in detail.
And once those embeddings are stored and searched at scale, the underlying retrieval infrastructure becomes the domain of vector databases, which I cover separately in the Vector Databases Complete Guide 2026.
Query Rewriting Cannot Fix Bad Chunking
There is an important limitation here. Imagine the correct policy states:
Annual plans can be refunded within 30 days, except for Enterprise contracts with individually negotiated terms.
But your chunking pipeline separates the exception from the main rule.
A beautifully rewritten query might retrieve:
“Annual plans can be refunded within 30 days.”
and completely miss:
“Enterprise contracts with individually negotiated terms are excluded.”
The rewritten query did its job.
The knowledge representation failed. That is why retrieval quality needs to be treated as a system:
Chunking → Query Understanding → Retrieval → Reranking → Context Selection
If your source documents are being split poorly, fix that layer first. My RAG Chunking Strategies Complete Guide 2026 covers fixed-size, recursive, semantic, layout-aware and hierarchical approaches in more detail.
When Query Rewriting Can Make RAG Worse
This is the part that often gets lost when advanced RAG techniques become fashionable. Every transformation creates another opportunity to distort the user’s intent.
Suppose a user asks:
“Can contractors access it?”
The conversation is about an internal analytics dashboard.
A careless LLM rewriter might produce:
“Can external contractors access the company’s analytics data?”
That sounds reasonable, but the model has introduced the word external. The user’s organisation may classify contractors differently.
The rewritten query is now more specific but potentially less accurate.
Other failure modes include:
Intent drift
The rewritten query subtly asks something different.
Over-expansion
Too many synonyms broaden retrieval beyond useful boundaries.
Hallucinated details
The rewriting model inserts entities, products, dates or assumptions that the user never supplied.
Duplicate retrieval
Multiple generated queries return almost identical documents.
Increased latency
Every rewrite or decomposition step adds computation.
Increased cost
LLM-based rewriting can become expensive at high query volumes.
Harder debugging
When an answer fails, you now need to determine whether the problem came from the original query, rewriting, retrieval, fusion, reranking or generation.
More sophisticated architecture creates more sophisticated failure modes.
A Practical Query-Rewriting Strategy
A rewritten query may look clearer without actually improving retrieval. The only reliable way to know is to compare the original and rewritten queries against the same evaluation set and measure whether relevant evidence appears more consistently and ranks higher, without changing the user’s intent.
Metrics such as Recall@K, MRR and context precision are useful here, followed by faithfulness and correctness checks on the generated answer. My RAG Evaluation Complete Guide 2026 explains how to build this kind of component-level RAG evaluation workflow.
I would not start by rewriting every query. Start by identifying the queries your current retriever handles poorly.
A practical progression is:
1. Establish the baseline
Measure retrieval quality using the original user query.
2. Identify failure patterns
Are failures mostly caused by:
- conversational references?
- ambiguous language?
- vocabulary mismatch?
- multi-part questions?
- very short queries?
3. Add the smallest useful transformation
For conversational ambiguity, use standalone rewriting.
For terminology mismatch, test expansion.
For complex questions, test decomposition.
For sparse semantic queries, evaluate multi-query retrieval or HyDE.
4. Preserve the original query
Do not throw it away. Keeping the original query alongside rewritten versions can protect against transformation errors.
5. Retrieve candidates
Use the appropriate lexical, vector or hybrid retrieval strategy.
6. Deduplicate and rerank
Multiple query variants can create duplicate and weak candidates. Reranking becomes increasingly valuable here.
7. Evaluate end-to-end
Do not judge success because the rewritten query sounds better. Measure whether it actually retrieves better evidence and produces more grounded answers.
That last step is critical. A query transformation is useful only when it improves the system’s outcome.
What Should You Measure?
Query rewriting should be evaluated at the retrieval layer before you celebrate improvements in final answers.
Useful retrieval metrics include:
- Recall@K – did the retriever find the relevant evidence?
- Precision@K – how much of the retrieved evidence was useful?
- MRR – how high did the first relevant result rank?
- nDCG@K – how well were the relevant results ranked?
Then evaluate the generation layer:
- answer relevance
- faithfulness
- groundedness
- context precision
- context recall
This distinction helps diagnose problems. If retrieval improves but answer quality does not, the bottleneck may have moved downstream.
If the answer improves while retrieval metrics remain flat, your evaluation set may not fully capture the system’s behaviour.
Our next planned article, RAG Evaluation Complete Guide 2026, will explore these metrics and evaluation frameworks in much greater depth.
Query Rewriting in Multi-Turn RAG
Conversational RAG is probably where query rewriting becomes most immediately useful.
A normal search query is usually expected to stand on its own. Conversation is different.
Consider:
User: Which database should I use for semantic search?
Assistant: [answer]
User: What if I have 50 million vectors?
Assistant: [answer]
User: And if metadata filtering is important?**
The third question makes perfect sense to a person following the conversation.
As an isolated search query, it is weak. A conversation-aware rewriter can combine the relevant history with the latest turn:
“Which vector database is suitable for approximately 50 million vectors when strong metadata filtering is required?”
That is much closer to the actual information need.
This problem is receiving substantial research attention in 2026 because real AI assistants increasingly operate across conversations rather than isolated questions.
What 2026 Research Tells Us
Recent multi-turn RAG research gives us a useful reality check.
Competitive SemEval-2026 systems have experimented with combinations of:
- contextual query rewriting
- query decomposition
- sparse retrieval
- dense retrieval
- Reciprocal Rank Fusion
- cross-encoder reranking
- answerability detection
- grounded generation
One particularly useful finding is that complexity does not always win.
A SemEval-2026 system using query rewriting, hybrid BM25+dense retrieval and cross-encoder reranking reported that some more elaborate strategies, including its multi-query expansion configuration, actually degraded performance during development.
That is a valuable engineering lesson. The goal is not to build the most complicated RAG diagram. The goal is to retrieve the strongest evidence with acceptable cost, latency and reliability.
Query Rewriting vs Reranking: Which Should You Add First?
They address different problems.
If you never include the right document in your candidate set, then reranking can’t rescue it.
If the right document is already there, but it is not ranked high enough, you may not need to rewrite it.
Think of it this way:
Query rewriting asks:
Are we searching for the right thing?
Retrieval asks:
Can we find potentially relevant evidence?
Reranking asks:
Which candidates are actually the most relevant?
That diagnostic approach is much more useful than blindly adding every fashionable RAG technique.
When Should You Use Query Rewriting?
Query rewriting is especially worth testing when your application contains:
- multi-turn conversations
- ambiguous follow-up questions
- domain-specific terminology
- short or underspecified queries
- complex comparison questions
- multi-hop questions
- mixed keyword and semantic retrieval
- large heterogeneous knowledge bases
You may not need it when:
- queries are already structured and explicit
- users search using controlled terminology
- retrieval quality is already high
- latency requirements are extremely strict
- the additional transformation does not improve evaluation metrics
Production RAG should be evidence-driven. If a simpler pipeline performs just as well, it is usually easier to operate.
From Query Rewriting to Agentic RAG
Query rewriting also reveals where RAG architecture is heading.
Traditional RAG assumes something like:
Ask → Retrieve → Generate
More advanced systems can do:
Understand → Rewrite → Retrieve → Inspect → Search Again → Compare → Select → Generate
At that point, retrieval is no longer a single fixed operation. The system is beginning to reason about how it should search. That is one of the foundations of Agentic RAG.
An agentic system may decide that:
- the query needs clarification
- several searches are necessary
- the first evidence is insufficient
- another source should be consulted
- conflicting evidence needs resolution or
- the system should abstain rather than answer
That deserves its own guide, and it is coming later in this RAG series after we cover RAG evaluation.
Final Thoughts
Query rewriting in RAG solves a deceptively simple problem:
Users do not always ask questions in the form your retrieval system needs.
A strong retriever cannot compensate for every ambiguous, incomplete or context-dependent query.
Rewriting provides the system with an intermediate layer to understand the information need before it searches. But it should not be treated as magic.
The strongest RAG systems increasingly combine multiple layers:
Good chunking → good query representation → strong retrieval → reranking → careful evidence selection → grounded generation → evaluation
Each layer solves a different failure mode. And that is probably the most useful way to think about advanced RAG in 2026.
The question is no longer simply:
“Which vector database should I use?”
It is:
“Where in my retrieval pipeline is useful information being lost?”
Query rewriting gives us one more place to find and resolve that problem.
Key Takeaways
- Query rewriting is a process that converts user questions into search-friendly retrieval queries.
- It is especially useful for conversational and context-sensitive queries.
- Query rewriting, query expansion, multi-query retrieval, and query decomposition address different retrieval problems.
- Query rewriting can improve hybrid search and cross-encoder reranking.
- Multiple query strategies can increase recall but can also introduce noise, latency and duplicates.
- Decomposition of queries is useful for complex and multi-hop information needs
- HyDE leverages generated hypothetical content to build a richer retrieval representation.
- Rewriting cannot improve poor chunking or missing source knowledge.
- Keep the original query to avoid rewriting errors and automatically replace user intent.
- Do not assume that a more sophisticated query is automatically better; instead, measure retrieval improvements.
- Another important building block for more dynamic Agentic RAG systems is query transformation.
Frequently Asked Questions
What is query rewriting in RAG?
Query rewriting is a technique that rewrites the original user query into a clearer or retrieval-friendly query before searching the knowledge base. This is particularly useful if the questions are ambiguous, conversational, or need context from an earlier question.
Does query rewriting improve RAG accuracy?
It can improve retrieval accuracy when the original query does not well represent the user’s information need. However, this improvement depends on the dataset, retriever, query type, and rewriting strategy and should be measured rather than assumed.
What is the difference between query rewriting and query expansion?
One way to reformulate the original question is by rewriting the query, while query expansion usually adds useful terms, synonyms or related concepts. They both aim to improve retrieval, but they address slightly different problems.
What is multi-query retrieval in RAG?
Multi-query retrieval produces several variants of a user query, retrieves documents for each variant, and merges the resulting candidate sets. It improves recall but also increases computation and retrieval noise.
What is query decomposition?
Query decomposition is a process of splitting a complex question into smaller searchable questions. It is useful for comparisons, multi-hop reasoning and questions that need evidence from multiple documents.
What is HyDE in RAG?
Hypothetical Document Embeddings, or HyDE, generates a hypothetical relevant document or answer from the query and uses its embedding to retrieve semantically similar real documents.
Should query rewriting happen before or after hybrid search?
Usually before retrieval. The rewritten query or queries are passed to lexical and/or vector retrievers. Their results can then be fused and reranked.
Is query rewriting necessary for every RAG system?
No. If users already submit clear, structured queries and retrieval performance is strong, rewriting may add unnecessary cost and latency.
References
- Meng, S. & Ilvovsky, D. – Sifei at SemEval-2026 Task 8: Hybrid Retrieval and Query Rewriting for Multi-Turn RAG, Association for Computational Linguistics, 2026.
- Raya-Rios, V. et al. – IIMAS-RAG at SemEval-2026 Task 8: Hybrid Sparse-Dense Retrieval and Answerability-Conditioned Generation for Multi-Turn RAG, Association for Computational Linguistics, 2026.
- Caraman, D. & Silaghi, G. C. – Three-Stage Multi-Turn Retrieval with Query Rewriting, Hybrid Search, and Cross-Encoder Reranking, Association for Computational Linguistics, 2026.
- Shrestha, S. & Aryal, S. – Query Reformulation and Dense-Lexical Retrieval Fusion for Multi-Turn Retrieval-Augmented Generation, Association for Computational Linguistics, 2026.
Author Bio
Amit Gupta is a UI/UX Designer and Frontend Specialist with more than 20 years of experience in product design, design systems, Angular development, frontend architecture, and emerging technologies. Through AmitGuptaBlogs.com, he shares practical insights on AI, Google technologies, design workflows, development tools, and future technology trends.