Table of Contents
A RAG system can produce an answer that looks excellent and still be failing underneath.
Maybe the right document was never retrieved. Maybe useful evidence appeared at position 18 and never reached the language model. Maybe the correct context was available, but the model ignored it. Or perhaps the answer happens to be correct even though the retrieved evidence does not support it.
This is why RAG evaluation needs to go deeper than just reading a handful of answers and deciding whether they ‘look right’.
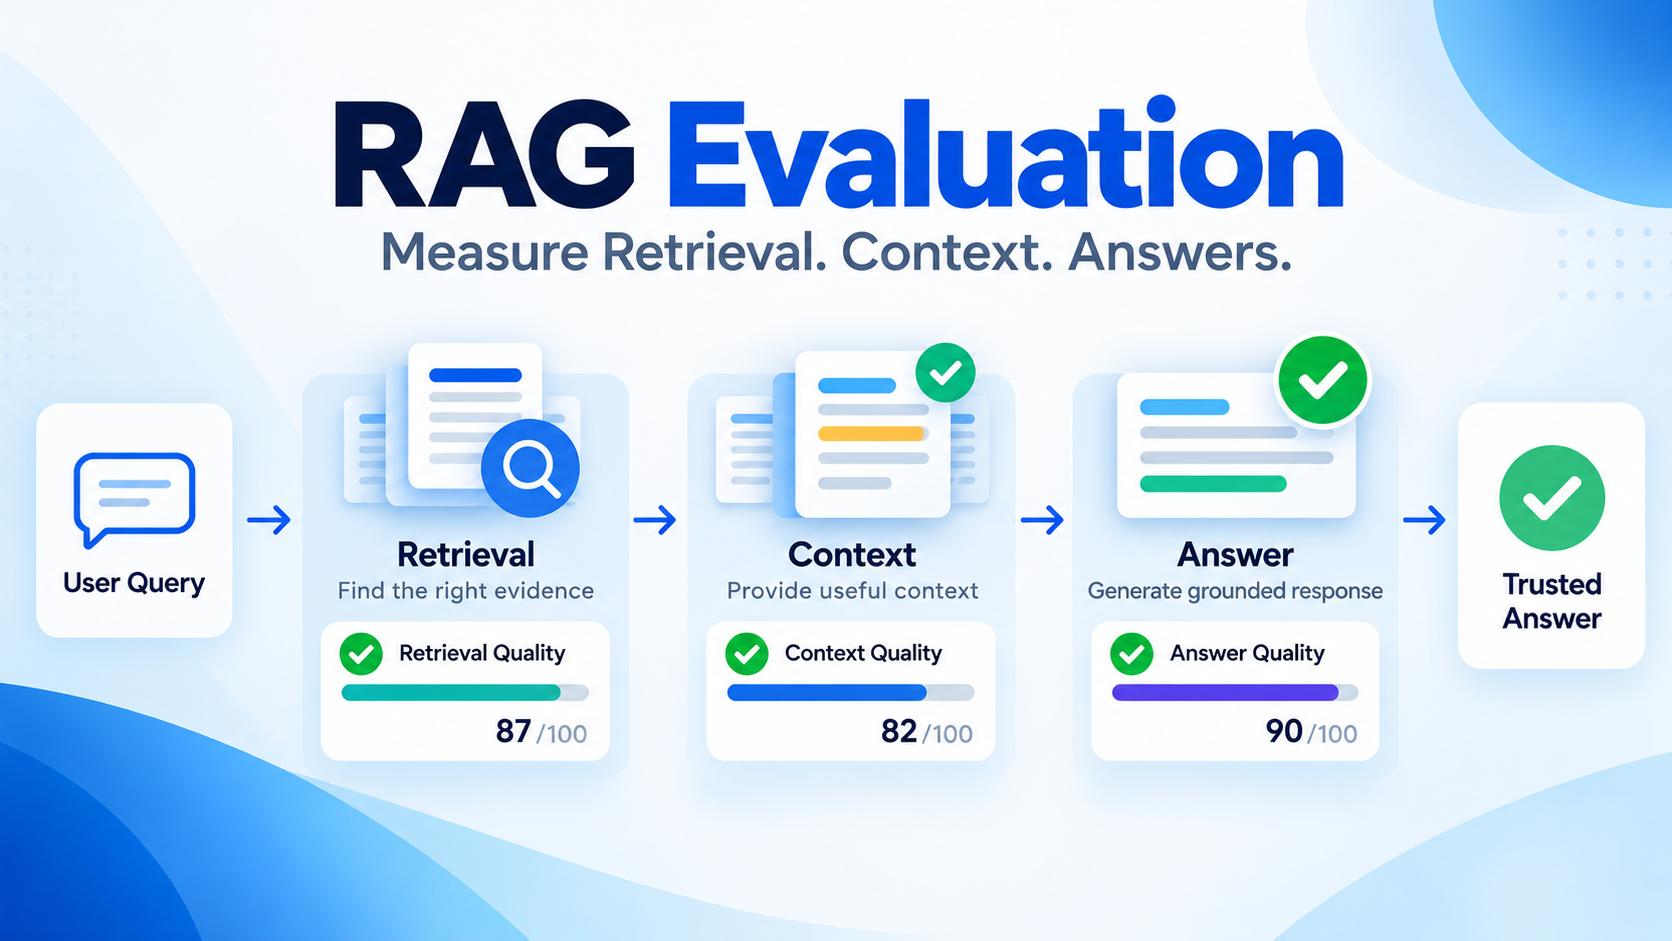
A useful evaluation strategy follows the same structure as the system itself:
Evaluate Retrieval → Evaluate Context → Evaluate Generation → Diagnose the Pipeline
Once you start thinking this way, improving RAG becomes much less about trying random embedding models, chunk sizes or prompts. You can identify where the failure actually started.
Why RAG Evaluation Is Harder Than It Looks
Imagine an internal HR assistant answering:
“How many days can an employee carry forward unused annual leave?”
It replies:
“Employees can carry forward up to 10 days.”
The answer sounds clear. It may even be factually correct.
But that tells us surprisingly little about the RAG pipeline.
The system might have retrieved an outdated policy. It might have retrieved the correct policy but missed an exception for a particular employee category. The model might have answered based on its own learned knowledge rather than the supplied evidence.
The scenario creates several distinct failure modes:
- correct evidence was never retrieved;
- relevant evidence was buried beneath weak results;
- too much irrelevant context reached the model;
- the correct evidence was retrieved but ignored;
- the model added unsupported details;
- query rewriting changed the user’s original intent;
- the answer was correct, but for the wrong reason.
That last case is particularly dangerous because ordinary manual testing may mark it as a success.
The underlying lesson is simple:
A RAG system is a pipeline, so its evaluation should also be a pipeline.
If you need the architecture behind that pipeline first, my Retrieval-Augmented Generation (RAG) Complete Guide 2026 explains how retrieval and generation work together before evaluation is added on top.
The RAG Evaluation Stack
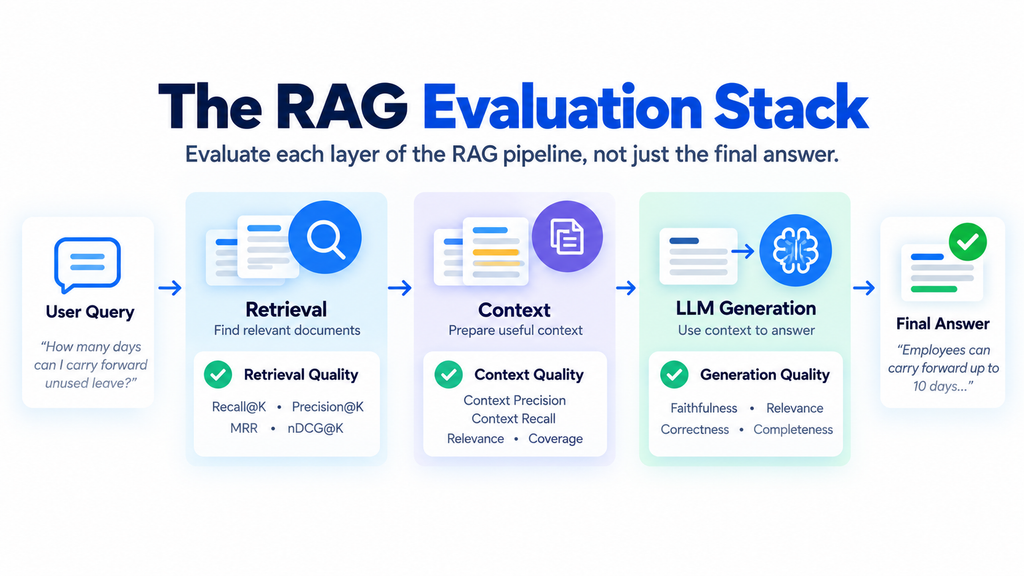
I find it useful to separate evaluation into three layers.
Retrieval quality asks: Did we obtain the evidence we needed?
Context quality asks: Did we give the LLM useful, sufficient and well-ranked evidence?
Generation quality asks: Did the LLM produce a relevant, correct and evidence-supported answer?
These questions sound similar, but they diagnose very different problems.
That distinction matters because an excellent language model cannot recover evidence that retrieval never found. Similarly, excellent retrieval cannot guarantee that the generator will use the evidence correctly.
Current evaluation systems increasingly reflect this separation. Microsoft, for example, distinguishes retrieval-process evaluation from final-response evaluation, while frameworks such as RAGAS and DeepEval provide metrics targeting different RAG components.
RAG Evaluation Metrics for Retrieval
Before judging the answer, evaluate what the search actually returned.
Suppose a question has two chunks in your knowledge base containing the evidence required for a complete answer. Your retriever returns five chunks.
What should you measure?
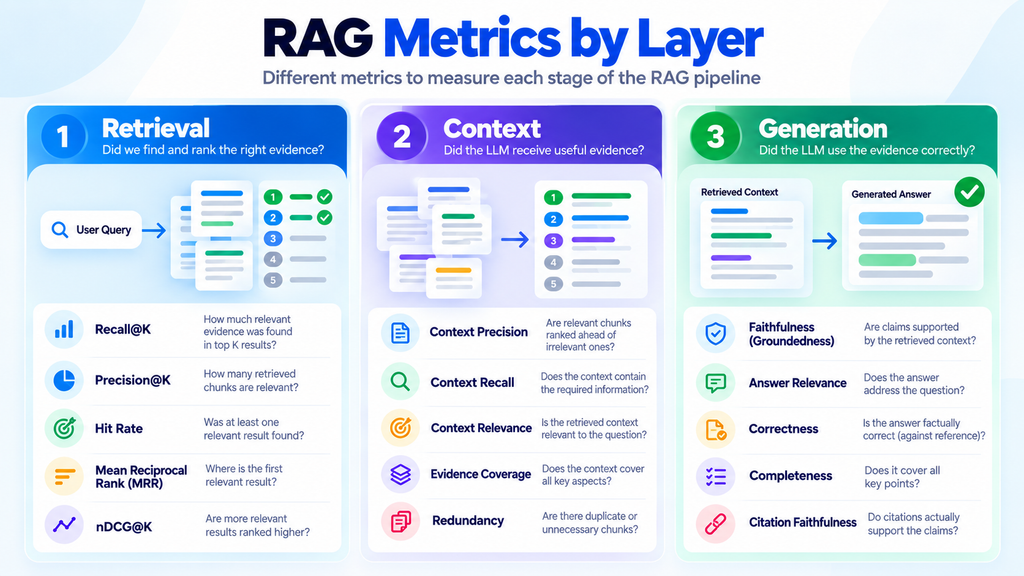
Recall@K
Recall@K asks how much of the relevant evidence appears in the first K retrieved results.
If both required chunks appear in the Top 5, recall is high. If only one appears, some evidence is already lost before generation starts.
This makes recall especially important in RAG.
The generator cannot reason over evidence it never receives.
If recall is consistently poor, investigate areas such as query formulation, embeddings, filters, indexing and retrieval strategy rather than immediately changing the LLM prompt.
This stage is also where combining lexical and semantic retrieval, as explained in my Hybrid Search Complete Guide 2026, can improve candidate discovery.
Precision@K
Precision asks a different question: How many of the Top-K results are actually relevant?
Suppose five chunks are retrieved, but only two help answer the question. Recall might still be excellent if those two contain all necessary evidence, while precision is poor because three unnecessary chunks were also returned.
Low precision matters because irrelevant context consumes tokens and can distract the generator.
Hit Rate
Hit Rate is useful when success means simply finding at least one relevant result.
For example:
Did at least one correct product manual appear in the Top 5?
It is intuitive and useful for broad monitoring, although it tells you less about ranking quality or whether all necessary evidence was found.
Mean Reciprocal Rank
MRR focuses on where the first relevant result appears.
If the first useful chunk appears at rank 1, that is better than finding it at rank 9.
MRR is especially useful when it is important to identify one strong answer-bearing result early. Microsoft’s current retrieval guidance also includes MRR among information-retrieval metrics.
nDCG@K
Not every result has to be simply “relevant” or “irrelevant”.
Some may be highly relevant, others partially useful.
nDCG@K rewards systems that place more useful results higher in the ranking, making it valuable when you have graded relevance labels rather than a simple yes/no judgement. Current Microsoft document-retrieval evaluation also exposes NDCG alongside other search-quality measurements.
The practical point is not to collect every metric available.
Choose metrics based on what retrieval success means for your application.
Retrieval Quality Is Not the Same as Context Quality
Finding a relevant document is only the beginning.
The final context supplied to the LLM may have gone through chunking, filtering, deduplication, reranking and Top-K selection.
That creates another evaluation layer.
Consider a policy document where one chunk says:
Employees may carry forward up to 10 unused leave days.
A nearby chunk says: Employees serving notice may not carry forward unused leave.
Retrieving only the first chunk looks successful at the document level, but the context is incomplete.
This is why your RAG chunking strategy can directly affect evaluation results. Splitting a rule from its exception can create failures even when retrieval appears superficially correct.
Context Precision
RAGAS defines context precision around whether relevant retrieved chunks are ranked ahead of irrelevant ones. It supports both reference-based and reference-free variants.
Practically, context precision asks: Are the strongest pieces of evidence near the top or buried among weaker chunks?
This connects directly with Reranking in RAG Complete Guide 2026. A retriever may identify the right evidence, while a reranker determines whether that evidence actually receives priority.
Context Recall
Context recall asks whether the retrieved context contains the information required to support the expected answer.
RAGAS currently supports LLM-based, non-LLM and ID-based approaches to context recall. Its LLM-based version checks whether claims from a reference answer can be attributed to retrieved context.
Think of the distinction this way:
Context precision: Did we bring too much noise?
Context recall: Did we leave important evidence behind?
Context Relevance, Redundancy and Conflict
Numbers alone are not enough.
Also inspect whether retrieved chunks:
- actually address the question;
- repeat essentially the same information;
- contradict one another;
- represent outdated versions;
- omit necessary exceptions;
- collectively cover the evidence required for an answer.
DeepEval’s current contextual relevancy metric, for example, evaluates how much of the supplied retrieval context is relevant to the user input.
This is one reason evaluation should happen after Query Rewriting in RAG Complete Guide 2026 techniques are introduced. A beautifully rewritten query that subtly changes user intent may retrieve relevant evidence for the wrong question.
Evaluate the Generated Answer Separately
Now we reach the part users actually see.
Several dimensions matter here, but three are particularly useful.
Answer Relevance
Does the answer actually address the question being asked?
A response can be grounded in the supplied documents and still ramble into unnecessary details.
Answer relevance catches that problem.
DeepEval, for example, treats answer relevancy as a referenceless generator metric comparing the generated response with the user input.
Faithfulness or Groundedness
The second metric asks:
Are the claims in the answer supported by the retrieved evidence?
RAGAS describes faithfulness as factual consistency between the response and retrieved context.
This is not the same as factual correctness.
That distinction deserves emphasis.
Correctness and Faithfulness Are Not the Same Thing
Consider this question: “When was Policy X updated?”
The retrieved context says nothing about the update date.
The model answers, “Policy X was updated in March 2026.”
Suppose March 2026 happens to be the correct date.
The answer can therefore be correct but unfaithful because the supplied evidence did not support that claim.
The reverse can also occur.
If the retrieved document contains an outdated date and the model accurately repeats it, the answer may be faithful to its context but factually wrong.
Microsoft’s current RAG guidance explicitly recommends considering groundedness and correctness together because the combination helps expose these different failure modes.
This is one of the most important ideas in RAG evaluation:
“Is the answer correct?” and “Is the answer supported by the retrieved evidence?” are two different questions.
For systems that show citations, you can go further and test whether each citation actually supports the claim attached to it, rather than merely pointing somewhere in the retrieved context. DeepEval, for example, now exposes a community citation-faithfulness metric for this stricter form of checking.
Reference-Based vs Reference-Free RAG Evaluation
Evaluation becomes easier when you already know the correct answer.
A reference-based test might contain:
- user question;
- expected evidence;
- reference answer;
- retrieved chunks;
- generated answer.
You can then compare what the system found and produced against known ground truth.
This is extremely useful for regression testing.
But production questions rarely arrive with labelled answers.
That is where reference-free evaluation becomes useful. Instead of asking whether an answer matches a predefined answer, you can evaluate properties such as:
- whether retrieved context is relevant;
- whether generated claims are grounded in context;
- whether the response addresses the question.
Neither approach completely replaces the other.
A strong evaluation programme typically maintains a curated reference dataset for controlled testing, while also monitoring real production interactions using metrics that do not require ground truth.
Where LLM-as-a-Judge Fits
Many modern RAG metrics use another language model to evaluate retrieved evidence or generated answers.
There is a good reason for this approach.
Qualities such as groundedness, relevance and completeness are difficult to capture with simple string matching.
LLM judges can make these evaluations far more scalable.
But LLM-as-a-judge is still an evaluator, not objective truth.
Research has documented position bias in LLM judges, with results varying across judge models and tasks.
In practice, scores can also depend on the evaluation rubric, prompt, judge model and output format.
Treat an LLM judge like a measurement instrument that needs calibration.
For important applications:
- define clear scoring criteria;
- test judges against human-labelled examples;
- inspect disagreement cases;
- keep judge models and prompts versioned;
- periodically re-evaluate your thresholds.
Human review becomes particularly valuable around ambiguous, high-impact or borderline cases.
RAGAS and DeepEval: Where Do They Fit?
You do not need an evaluation framework to understand RAG quality, but such frameworks make repeated evaluation much easier.
RAGAS
RAGAS provides metrics covering RAG and increasingly broader LLM and agentic evaluation.
Its current RAG metric set includes context precision, context recall, context entities recall, noise sensitivity, response relevancy and faithfulness, as well as multimodal measures. It also includes metrics for tool use and agent workflows.
For a RAG practitioner, its main value is giving structure to questions such as:
Did I retrieve enough evidence?
Did I rank useful evidence well?
Did the answer remain faithful to it?
DeepEval
DeepEval similarly separates retriever and generator evaluation.
Its current RAG guidance emphasises contextual relevancy, contextual precision and contextual recall for retrieval, with answer relevancy and faithfulness for generation. It also provides multi-turn counterparts for conversational RAG evaluation.
The important point is not deciding which framework has the longest metric list.
Choose the framework that fits your testing stack, observability requirements and evaluation workflow.
The mental model should remain valid even if you use neither.
A Practical RAG Evaluation Workflow
Here is the workflow I would start with.
Step 1: Build an Evaluation Dataset
Collect representative questions rather than only easy examples.
Include straightforward lookups, multi-document questions, ambiguous wording, queries requiring exceptions, follow-ups and cases where the system should admit that evidence is unavailable.
For each test, record expected evidence and a reference answer where practical.
Step 2: Evaluate Retrieval
Run the questions through retrieval without worrying about answer generation yet.
Ask: Did the correct evidence enter Top-K?
Measure metrics such as Recall@K, Precision@K, MRR or nDCG depending on the task.
Step 3: Evaluate the Final Context
Inspect what actually reaches the language model after filtering and reranking.
Ask: Is the context relevant, sufficient, correctly ranked and non-redundant?
Step 4: Evaluate Generation
Now evaluate the answer.
Ask: Is it relevant? Is it complete? Is it correct? Is every factual claim supported by the evidence?
Do not collapse these into one vague “quality” score.
Step 5: Diagnose the Failure
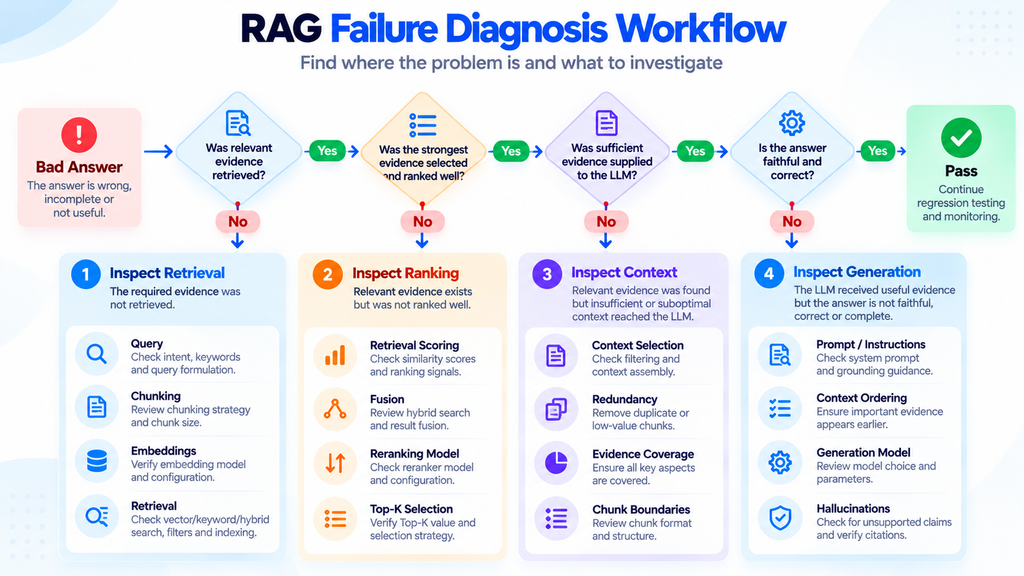
Map the failure back through:
Query → Chunking → Retrieval → Reranking → Context → Generation
Step 6: Change One Component
If retrieval recall is poor, changing the generation prompt probably teaches you very little.
Change the component most closely associated with the failure.
Step 7: Run the Same Evaluation Again
This is where evaluation becomes engineering rather than experimentation by instinct.
Keep the benchmark stable enough to compare versions and add new failure cases as you discover them.
Microsoft’s current guidance similarly recommends preserving experiment hyperparameters and evaluation results because RAG evaluation is an iterative process rather than a one-time test.
RAG Failure-Diagnosis Table
| Symptom | Likely Layer | What to Investigate |
|---|---|---|
| Correct document never appears | Retrieval | Query, embeddings, filters, vector/keyword/hybrid search |
| Relevant evidence exists but query misses it | Query understanding | Query rewriting, terminology, intent preservation |
| Correct chunk appears too low | Ranking | Retrieval scoring, fusion, reranker |
| Too much irrelevant evidence reaches LLM | Context | Top-K, filters, reranking, chunk size |
| Rule appears without its exception | Knowledge preparation | Chunk boundaries, parent-child retrieval |
| Correct evidence is retrieved but answer misses part of it | Generation / context use | Prompt, completeness, context ordering |
| Answer includes unsupported details | Generation | Faithfulness, grounding instructions |
| Answer is grounded but factually outdated | Source data | Corpus freshness, document versioning |
| Follow-up retrieves unrelated evidence | Conversational retrieval | Query rewriting, conversation state |
| Citations point to weak supporting passages | Generation / citation layer | Citation attribution and evidence mapping |
This table is often more useful than chasing a single overall evaluation score because it tells you where to investigate next.
Do Not Optimise What You Have Not Diagnosed
It is tempting to respond to a bad RAG answer by changing everything.
Try a different embedding model.
Increase Top-K.
Change chunk size.
Add a reranker.
Rewrite the prompt.
That may improve one example while quietly making ten others worse.
A better approach is to establish a baseline, identify the failing layer, change one meaningful variable and rerun the same evaluation set.
Over time, your evaluation dataset becomes more valuable because it starts capturing the actual ways your application fails.
And that becomes even more important as RAG architectures become dynamic.
In an Agentic RAG system, the application may reformulate a query, perform multiple searches, select tools, inspect results and decide whether more evidence is required. Microsoft’s current guidance already notes additional evaluation dimensions for agentic RAG, including tool-selection accuracy, retrieval efficiency and latency across reasoning steps.
We will explore that architecture separately.
For now, the principle worth keeping is simpler:
Do not optimise a RAG system until you know which layer is failing.
Good RAG Evaluation turns retrieval-augmented generation from trial-and-error into measurable engineering.
Frequently Asked Questions
What is RAG evaluation?
RAG evaluation measures how effectively a retrieval-augmented generation system retrieves evidence, prepares useful context and generates relevant, correct and grounded answers. Strong evaluation measures these components separately rather than judging only the final response.
What metrics should I use to evaluate RAG?
For retrieval, common metrics include Recall@K, Precision@K, Hit Rate, MRR and nDCG. For context and generation, useful dimensions include context precision, context recall, relevance, faithfulness or groundedness, and answer correctness and completeness. Choose metrics based on your application, rather than trying to maximise every available score.
How do you measure retrieval quality in RAG?
Start with a dataset containing queries and known relevant documents or chunks. Then measure whether relevant evidence appears within Top-K and how highly it is ranked using metrics such as Recall@K, Precision@K, MRR and nDCG.
What does faithfulness mean in RAG evaluation?
Faithfulness measures whether claims in the generated answer are supported by the retrieved context. An answer can be factually correct but still unfaithful if the retrieved evidence does not support what the model says.
What is context precision?
Context precision evaluates whether useful retrieved chunks are prioritised over irrelevant ones. High context precision generally means the context supplied to the model contains stronger evidence with less distracting material.
What is the difference between RAGAS and DeepEval?
Both provide structured evaluation capabilities for RAG and LLM applications. RAGAS includes metrics such as context precision, context recall, response relevancy and faithfulness, while DeepEval provides contextual retrieval metrics alongside answer relevancy and faithfulness plus broader testing and tracing capabilities. The appropriate choice depends on your evaluation workflow and development stack.
Can an LLM evaluate another LLM’s RAG answers?
Yes. LLM-as-a-judge can scale evaluation of qualities such as relevance, faithfulness and completeness, but judge results should not automatically be treated as objective ground truth. Important evaluations should be calibrated against human-labelled examples and periodically checked for bias and consistency.
How do I build a RAG evaluation dataset?
Start with representative real-world questions and record expected evidence plus reference answers where feasible. Include simple queries, multi-evidence questions, ambiguous cases, follow-ups, exceptions and cases where no answer should be available. Add newly discovered production failures to the dataset over time.
References
- RAGAS: current RAG and LLM evaluation metrics.
- DeepEval: RAG evaluation metrics covering retrieval, generation and multi-turn evaluation.
- Microsoft Azure Architecture Center: RAG solution design and end-to-end evaluation guidance.
- Microsoft Foundry: current retrieval, groundedness, relevance and document-retrieval evaluators.
- Shi et al., Judging the Judges: A Systematic Study of Position Bias in LLM-as-a-Judge.
- Saad-Falcon et al., ARES: An Automated Evaluation Framework for Retrieval-Augmented Generation Systems.
Author Bio
Amit Gupta is a UI/UX Designer and Frontend Specialist with more than 20 years of experience in product design, design systems, Angular development, frontend architecture, and emerging technologies. Through AmitGuptaBlogs.com, he shares practical insights on AI, Google technologies, design workflows, development tools, and future technology trends.